Introduction to
Personalized Medicine Samples
Personalized Medicine Samples for Biomarker-Led Precision Medicine Research
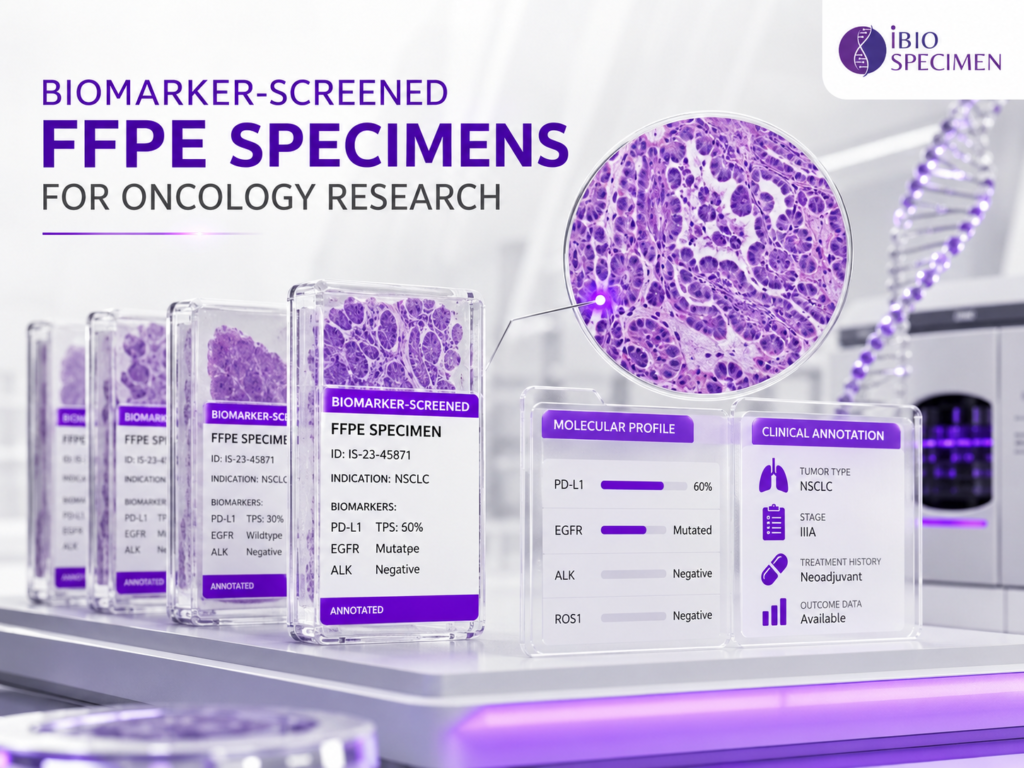
For pharmaceutical, biotechnology and AI teams, Personalized Medicine Samples is most valuable when it is built as a study-ready resource rather than a loose collection of files or specimens. In practice, the resource may combine pathology data, molecular characterization, clinical metadata, oncology research, depending on the study objective. The design should reflect whether the priority is broad discovery, disease-specific analysis, model pretraining, biomarker enrichment or independent validation. A useful starting point is to define the biological question first and then decide which images, specimens and metadata are required to answer it.
For molecularly focused studies, cases may be selected by mutation, copy-number alteration, expression profile, immunohistochemistry result or another pre-specified biomarker. Conversely, tightly controlled cohorts can be assembled when the scientific question requires a narrow biomarker-defined or treatment-defined population. Where appropriate, pathology review can confirm diagnosis, tumor content, necrosis, tissue adequacy and the relationship between the specimen and the corresponding digital image. Structured identifiers are important because images, blocks, molecular results and clinical variables must remain linked to the correct donor and specimen without ambiguity.
Molecular Characterization and Clinical Annotation of Personalized Medicine Samples
A high-value biospecimen resource is useful only when the underlying cases are scientifically coherent, traceable and structured for the intended research question. Quality is created through consistent linkage between pathology data, molecular characterization, clinical metadata and a structured case record. Each case should have a clear provenance trail showing how the diagnosis, specimen, digital asset and derived measurements relate to one another. Pathology and metadata review are particularly important before model training or downstream statistical analysis begins.
A consistent data dictionary reduces downstream engineering work by defining units, permissible values, missing-data conventions and relationships between case-level and specimen-level fields. The resulting resource can support reproducible analysis because the biological material, digital assets and metadata are assembled under one auditable case structure. For molecularly focused studies, cases may be selected by mutation, copy-number alteration, expression profile, immunohistochemistry result or another pre-specified biomarker. The cohort can be divided into development, validation and independent test sets when the project requires controlled model evaluation.
How Personalized Medicine Samples Supports Targeted Therapy and Translational Studies
For pharmaceutical, biotechnology and AI teams, Personalized Medicine Samples is most valuable when it is built as a study-ready resource rather than a loose collection of files or specimens. Personalized Medicine Samples can support research questions that are difficult to address with a single data modality. By combining pathology data, molecular characterization, clinical metadata, oncology research, investigators can study relationships that would otherwise remain hidden in separate data silos. The most valuable applications are those in which the cohort definition and analytical endpoint are specified before large-scale data generation begins.
AI developers can use it for supervised learning, self-supervised pretraining, fine-tuning, external validation or multimodal model development. For molecularly focused studies, cases may be selected by mutation, copy-number alteration, expression profile, immunohistochemistry result or another pre-specified biomarker. When multiple modalities are linked at case level, the same cohort can support both image-based analysis and integrated computational biology workflows. For this type of project, oncology research should be captured in a standardized form so it can be filtered, audited and reused consistently across the study.
Custom Precision Medicine Sourcing, Cohort Design and Quality Control
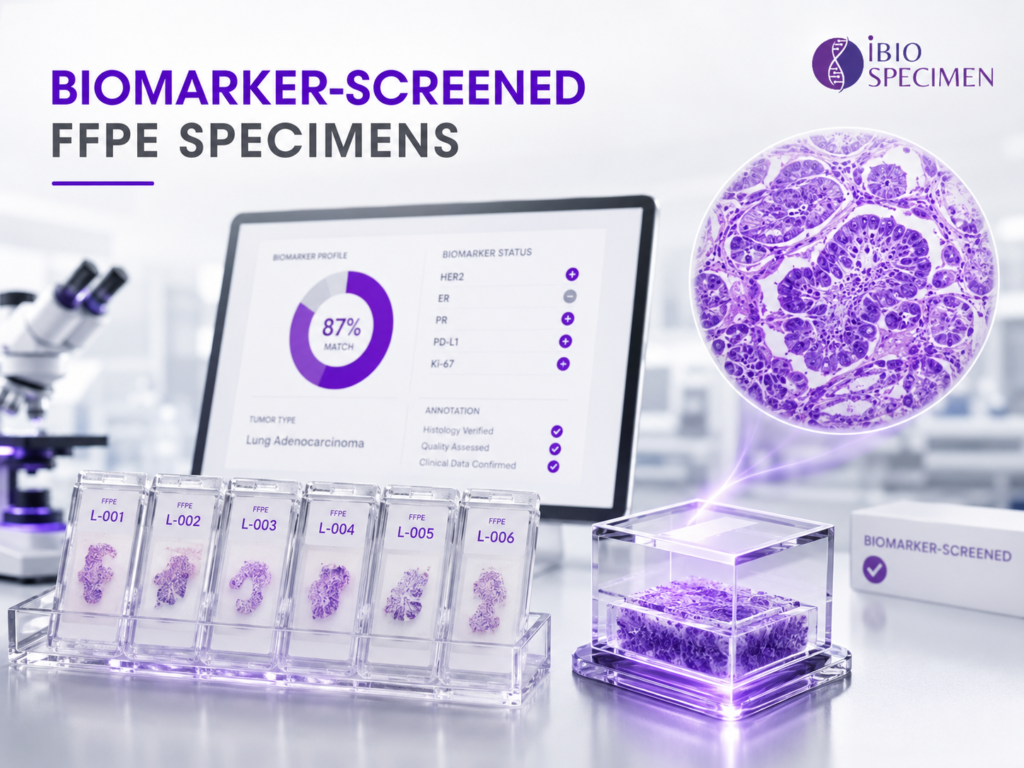
For pharmaceutical, biotechnology and AI teams, Precision Medicine is most valuable when it is built as a study-ready resource rather than a loose collection of files or specimens. Commercial development of Precision Medicine should be approached as a controlled sourcing and data-engineering program rather than a one-time file transfer. The specification can define target indications, sample counts, biomarker groups, slide requirements, metadata fields and acceptance criteria before case identification starts. A pilot batch is often useful for checking the practical fit between the source material and the receiving team’s analytical pipeline.
Cases can be organized by indication, histologic subtype, stage, grade, specimen type, collection period and other protocol-defined variables. For multi-site programs, harmonized naming, metadata standards and quality thresholds are especially important because local laboratory practices may differ. Quality control should address missing fields, conflicting biomarker values, duplicated cases, poor image quality and any mismatch between pathology reports and structured metadata. Structured identifiers are important because images, blocks, molecular results and clinical variables must remain linked to the correct donor and specimen without ambiguity.
General Questions
Frequent Asked Questions!!
FFPE blocks for genomics are formalin-fixed, paraffin-embedded tissue samples used for DNA, RNA, and biomarker analysis. They are widely used in cancer genomics, molecular pathology, translational research, and retrospective studies.
FFPE tissue blocks are valuable because they preserve tissue architecture and molecular material for long-term storage. Researchers can use them for sequencing, mutation analysis, biomarker discovery, and validation studies.
Yes. DNA can be extracted from FFPE blocks using validated extraction kits and optimized laboratory protocols. DNA quality depends on fixation time, block age, tissue type, tumor content, and storage conditions.
Yes. RNA can be extracted from FFPE tissue, although it is often fragmented because of formalin fixation. Specialized FFPE RNA extraction methods can provide material suitable for targeted RNA sequencing, gene expression studies, and fusion analysis.
Yes. High-quality FFPE blocks are commonly used for next-generation sequencing, including targeted sequencing panels, whole-exome sequencing, RNA sequencing, and selected whole-genome applications.
Tumor content requirements depend on the study design and testing method. Many molecular and NGS studies require at least 20% tumor content, while some projects may require 30%, 50%, or higher tumor percentage. Pathologist review can be performed to confirm tumor content before shipment
FFPE blocks can support mutation testing, copy number analysis, gene fusion detection, microsatellite instability testing, tumor mutational burden analysis, methylation studies, and targeted DNA or RNA sequencing.
Yes. FFPE cancer tissue blocks are extensively used to study genomic alterations in lung, breast, colorectal, prostate, ovarian, pancreatic, liver, kidney, and other tumor types.
Researchers can purchase FFPE blocks from qualified biospecimen suppliers, biobanks, pathology laboratories, hospitals, and research networks that provide ethically sourced and clinically annotated human tissue samples.
Researchers should confirm diagnosis, tissue type, tumor percentage, necrosis percentage, fixation details, block age, specimen size, available clinical data, pathology review, consent status, and intended research-use permissions.
Yes. Clinically annotated FFPE blocks may include donor age, sex, diagnosis, grade, stage, TNM classification, treatment history, pathology report, mutation status, and clinical outcome data.